
ISE Developer Blog
Solving global tech challenges, sharing insights, and empowering developers
Latest posts
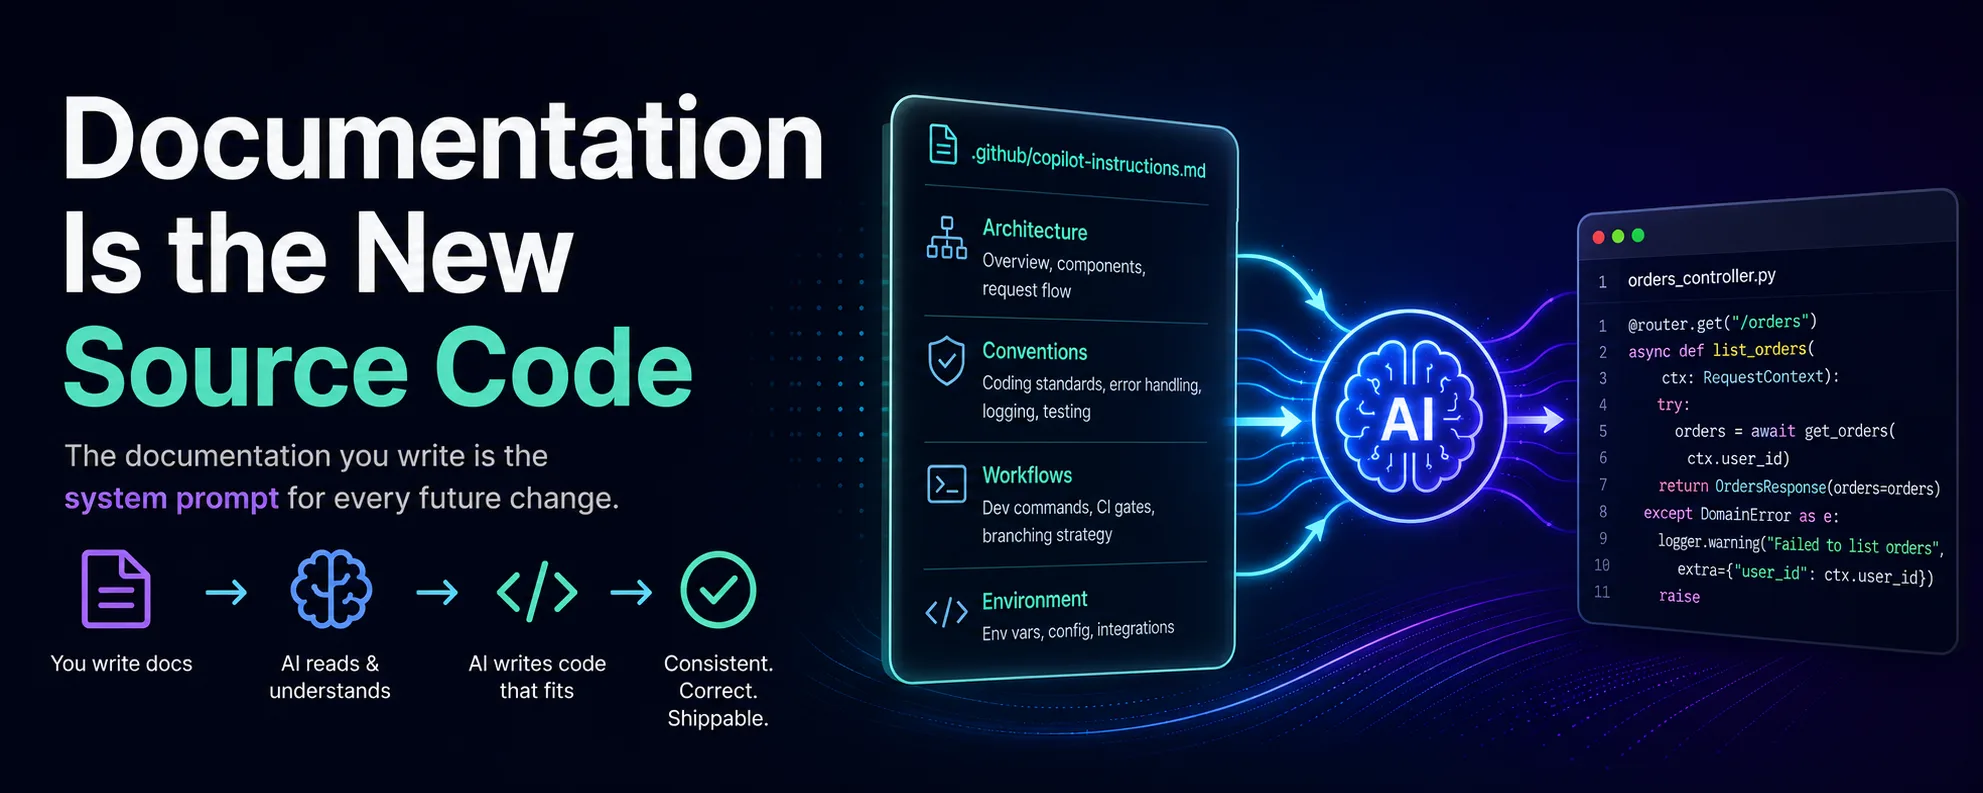
Documentation Is the New Source Code

A field guide to building a layered, AI-readable documentation system — instruction files, skills, ADRs, and tests — that turns your repo into a reliable substrate for Copilot, agents, and high-velocity engineering workflows.
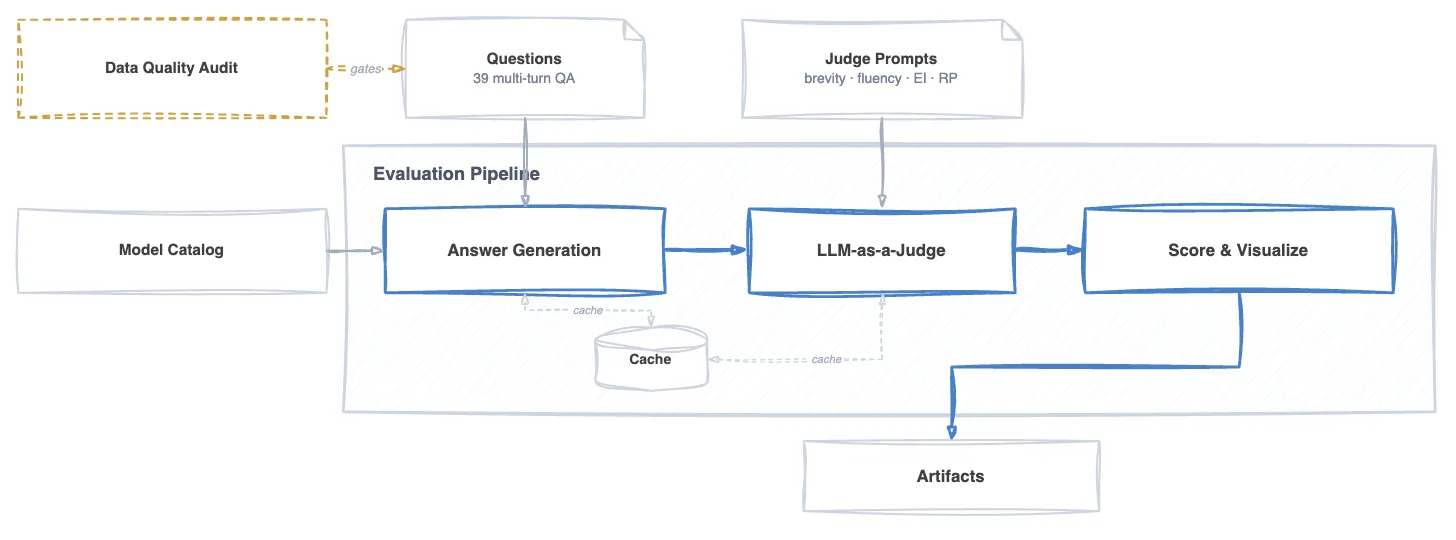
Building a Japanese LLM Evaluation Pipeline: Lessons from a Two-Day Hackathon


ISE hackathon produced a reusable Japanese LLM evaluation pipeline with multi-turn, facet-based scoring, cross-provider model support, and publication-ready benchmarking outputs.

Teaching a Vision Model to See Like a Human Annotator—and Catching It When It Lies


A multimodal LLM enrichment pipeline that extracts structured metadata from visual assets, constrains output to predefined values to minimize hallucinations, and uses a ground truth evaluation template to measure quality—all as a plug-and-play module.

From Noisy Queries to Precise Frames: Query Decomposition for Media Asset Search
How query decomposition separates metadata filters from visual intent to significantly improve media asset retrieval quality.

Enabling MLflow OpenAI Autolog on PySpark Workers

When distributing LLM calls across PySpark workers via mapInPandas, MLflow autolog silently fails. Here is how to fix it.

Passing Context Between Agents in Multi-Agent A2A Systems


How we solved the challenge of passing conversational context between independently deployed agents using the A2A protocol's embedded context pattern, keeping domain agents stateless and secure.

Separating Deterministic Extraction from AI Inference in Industrial Summarization

When 100% of our prototype outputs were valid JSON but 0% met the data contract, we discovered the LLM was doing work that software should own. A field classification exercise and 4-pass pipeline brought schema compliance from 0% to 100%.
Orchestration Patterns for Multi-Agent Systems: Performance and Trade-offs

Real-world lessons from evolving a production chatbot into a coordinator-based multi-agent architecture, including performance trade-offs for enterprise-scale agent reuse.

How we Decide Between Keyword and Hybrid Search: 5 Enterprise Evaluation Criteria

A data-driven framework we use in enterprise deployments to decide between vector-only keyword and hybrid search, based on five measurable evaluation criteria.